
One sentence, one video — no footage, no sign-up
Say one sentence and the AI makes a moving video on the spot.
People often say Make a 10-second birthday greeting with colorful balloons floating upCut the first 10 seconds and add a title cardAdd subtitles to this clip
You say:
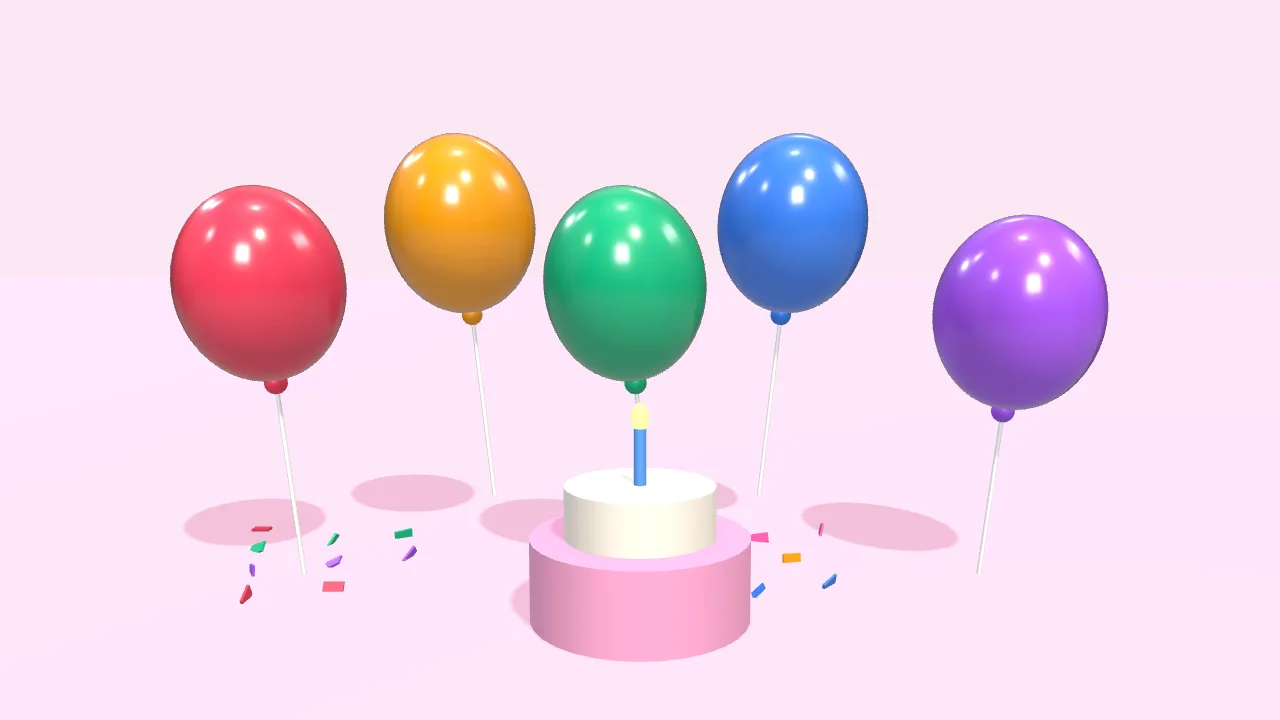
Make a 10-second birthday greeting: colorful balloons float up, then “Happy Birthday” appears
- Set up a 3D scene
- Add 5 balloons that float up
- Add a cake and falling confetti
- Add the text with a pop-in
- Export the 10-second video
You say:
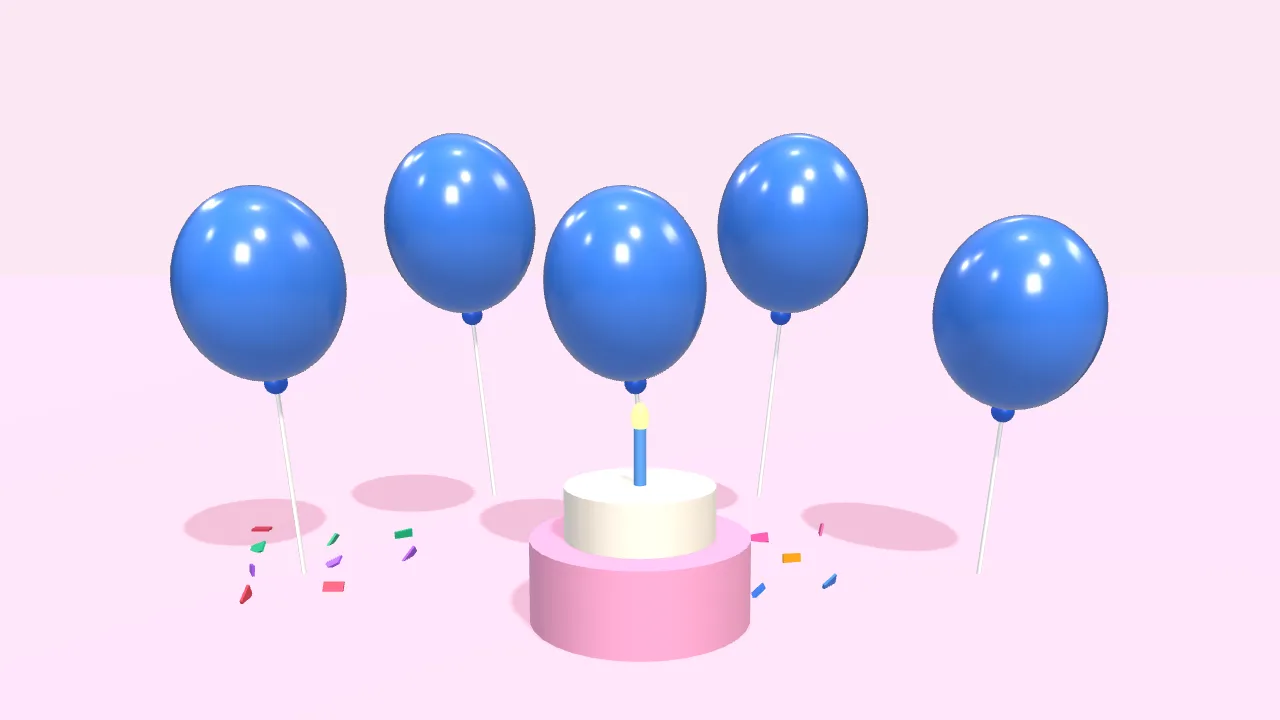
Bigger text in yellow, and make the balloons blue
- Larger font size
- Color white → yellow
- Balloons → blue
You say:
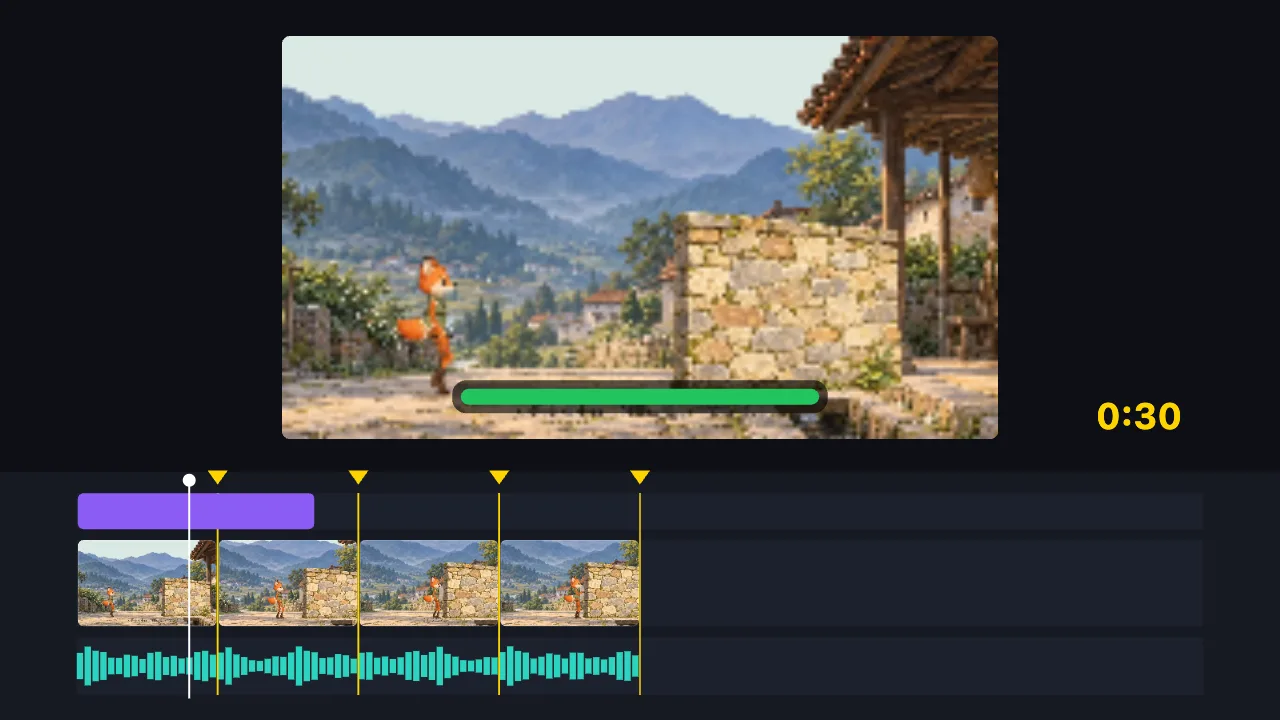
Cut this 2-minute clip to 30 seconds on the music beats, and add a title
- Find the music beats
- Split into 8 parts on the beats, drop the dull ones
- Add the title
- Export the 30-second video
You say:
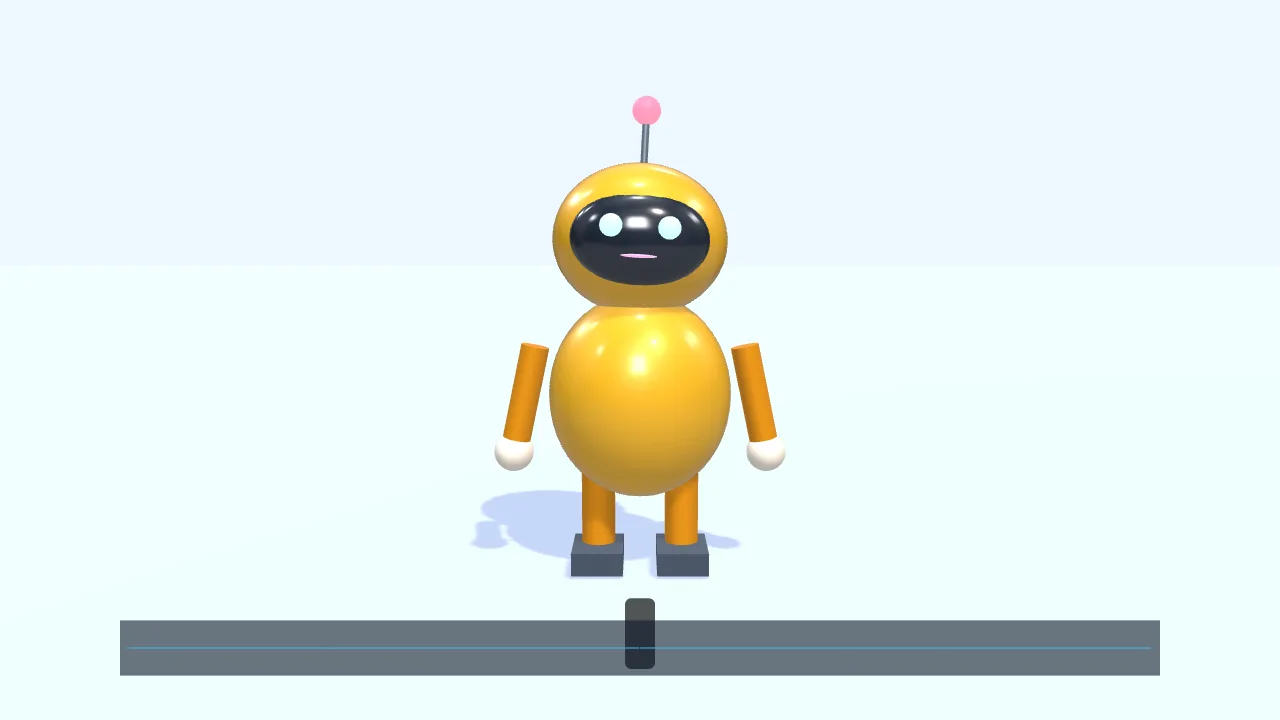
Have a character walk in from the left and talk along with this voice clip
- Add a small 3D robot
- Walk to the center and wave
- Drop in a voice clip
- The mouth opens and closes with the voice
- Add subtitles
You say:
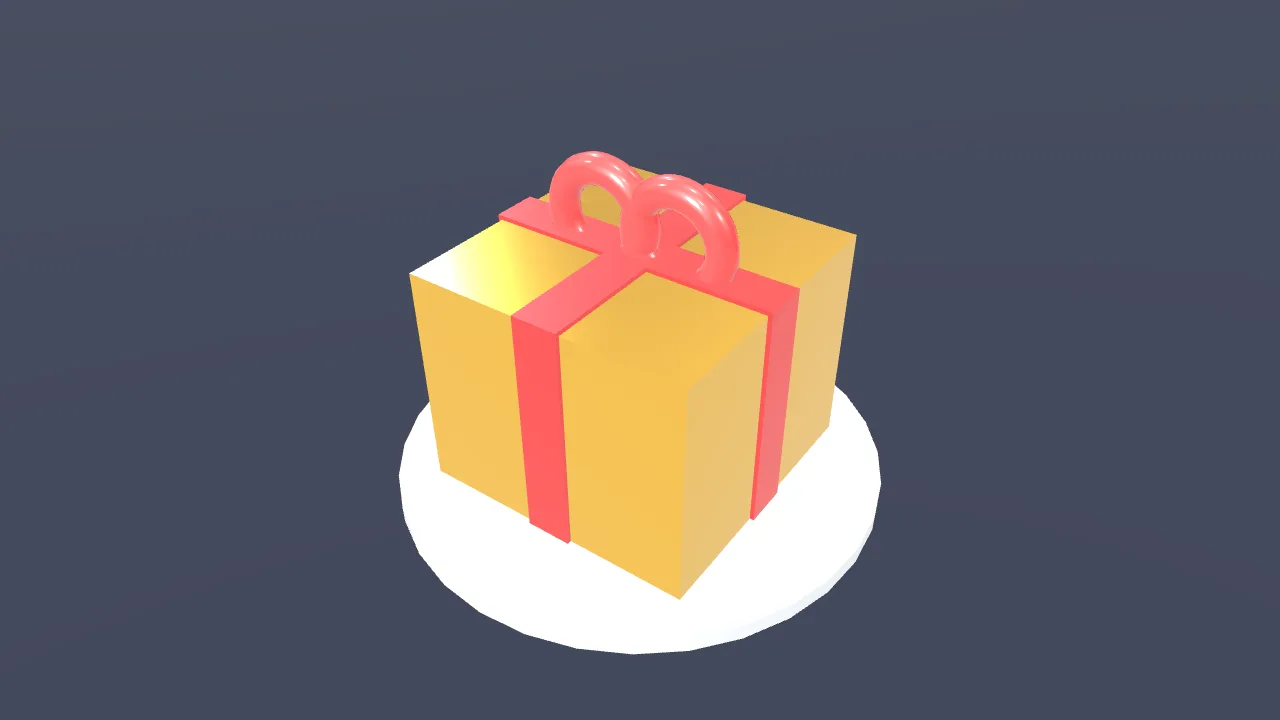
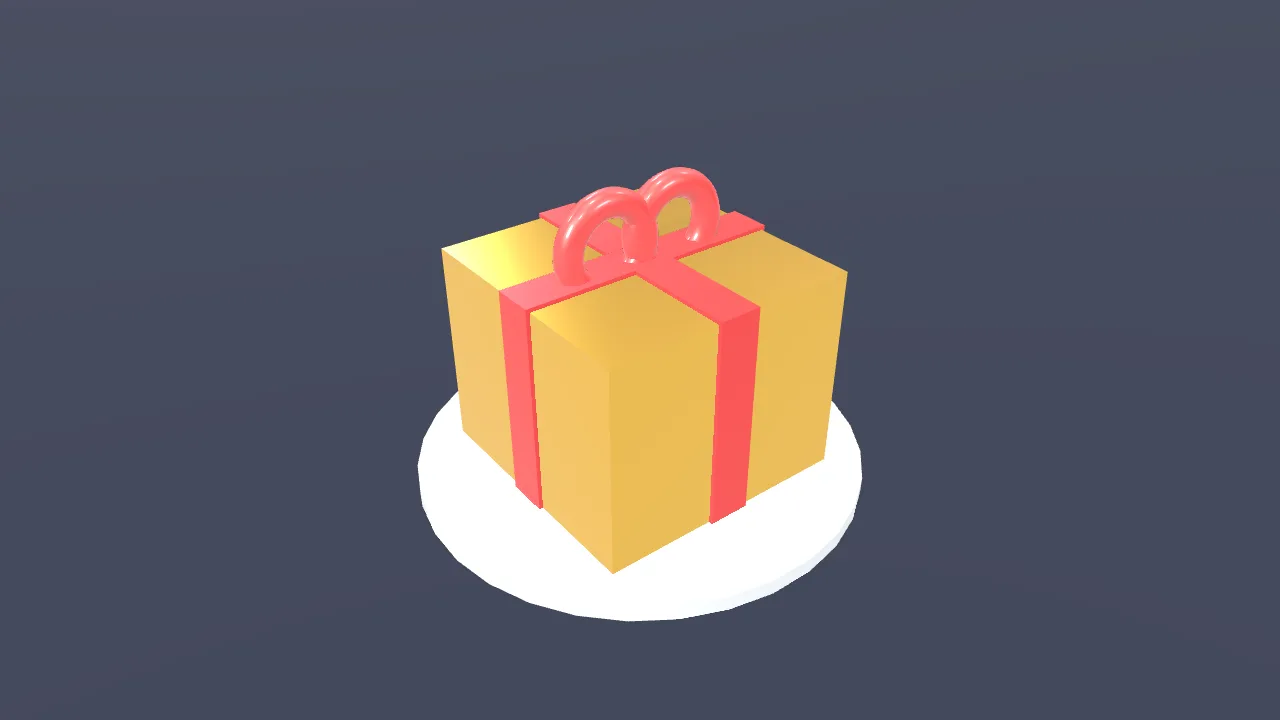
Make a gold gift box spin once, then show “New arrival”
- Create a 3D scene
- Add a gift box
- Give it a gold metal finish
- Add two lights
- Spin it once
- Show “New arrival”
You say:
Add a “New arrival” title animation over the gift box
- Add a built-in title motion
- Set the title to “New arrival”
- Export the 8-second video
No video-generation model and no queue: the AI writes a timeline, and your browser draws it.
The AI can’t: generate real live-action footage · fix blurry video · remove existing watermarks · create a 3D model file from nothing
Say one sentence and the AI makes a moving video on the spot — no footage, no queue, no sign-up. Motion graphics, 3D scenes, a character that walks and talks, and text animation are drawn in your browser, so results show in seconds, with no watermark. It does not make live-action footage.
Type “make a 10-second birthday greeting: colorful balloons float up, then ‘Happy Birthday’ appears”, and a few seconds later you are watching the result.
There is no queue because it is not running a video generation model. What the AI does is write a timeline: which shape, character or 3D object appears at which second, how it moves, what text shows, which transition joins the parts — and the engine in your browser draws it.
What it works with: motion graphics (shapes, drawn-on paths, text, with keyframes and easing), 3D scenes (basic shapes, materials, lights, camera, physics, plus your own .glb models), a character that walks and talks, bone animation, frame-by-frame drawing, and 6 templates, text animation, 26 filters, 13 transitions and 20 effects. There is no stock library of characters, scenes or props.
Every part of it stays yours to change — what it makes is an ordinary project, so open the editor and change whatever you like. Not happy with it? Just say “try another version”; no need to describe it all again.
FAQ
- Do I really not need to sign up?
- No. Making, changing and exporting videos need no account. Sign-in is only for cloud storage and the AI features that go through TutuDrive (having the AI listen to audio for subtitles, placing generated images on the timeline).
- Does the video have a watermark?
- No. You get a clean MP4 you can publish directly, as many times as you like.
- How long can the video be?
- No length limit is set. In practice 15–60 seconds works best; much longer tends to feel repetitive.
- Can it make a video with real people on camera?
- No. This site does not generate live-action footage. What it makes is motion graphics, 3D scenes, drawn characters and text animation — closer to illustration, motion design and simple 3D product shots than to photographic realism.
- Can I change it afterwards?
- Yes, every part. It is an ordinary project: text, shapes, characters, movement, timing and colors can all be adjusted by hand, or you can keep telling the AI things like “make the text bigger”.
- Why do other AI video sites make you wait in a queue?
- Because they run a diffusion model to generate every frame, which takes a lot of GPU time, so you queue. Here the AI writes a timeline and your browser draws the frames — light enough to finish on the spot. The trade-off is that the look is drawn, not photographic.